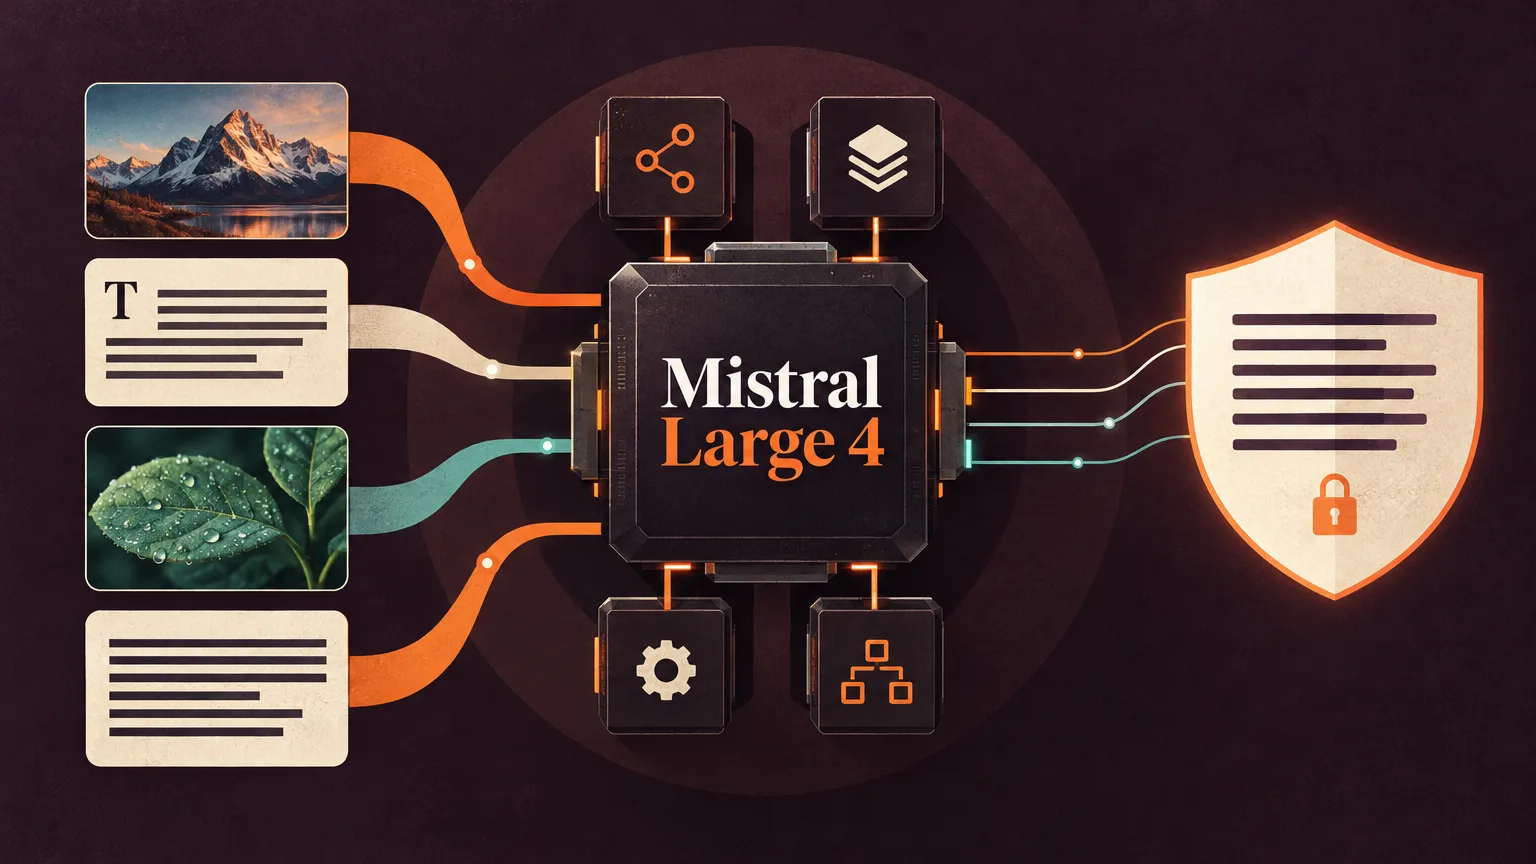
Mistral has released Large 4, a multilingual open-weight model that takes text and images as input and generates text. Nicknamed Le Chonk, it has a one-million-token context window and is aimed primarily at defensive cybersecurity. Developers can deploy it themselves or use it through a remote service.
Image input and expert architecture
Large 4 has roughly one trillion parameters, with 49 billion active. According to Hugging Face, its architecture combines expert networks and sparse attention with a Pixtral vision encoder for processing images.
Hugging Face says the model selects four of its 128 experts for each token and always runs a shared expert alongside them.
Security and coding results
Large 4 scored 82% on an Artificial Analysis Cyber Index task requiring it to reproduce and fix a real vulnerability in open-source software, according to Hugging Face. Mistral says its internal testing also found the model useful for analyzing malware, prioritizing vulnerabilities and writing detection rules, although it had not been explicitly trained for those tasks.
Hugging Face reports that Large 4 solved 93% of 40 security competition challenges in Cybench and achieved 93.3% attack resistance in Lakera B3. On cybersecurity prompts from JailbreakBench, StrongREJECT and AgentHarm, it had a higher average refusal rate than the other open-weight models tested.
In coding tests, Hugging Face reports scores of 61.7% for DeepSWE v1.1, 59.4% for SWE-Atlas-QnA and 28.3% for Terminal-Bench 4. Large 4’s overall result of 49.8% in the Coding Agent Index puts it ahead of both DeepSeek V4 Pro 0813 and Qwen3.8 Max.
For tests of business workflows and longer-term professional tasks, Hugging Face reports 59.9% on AutomationBench and 1,393 Elo on AA-Briefcase.
Variants and deployment options
The official weights are available in FP8 and NVFP4 variants under the Mistral Ecosystem Open-Weight License, which restricts model-as-a-service offerings. Unsloth and the llama.cpp team have also created GGUF versions.
Transformers, vLLM and llama.cpp support the model from release. NVFP4 uses less memory and requires NVIDIA Blackwell GPUs when run with vLLM. Hugging Face says the llama.cpp team’s two-bit quantized versions can run on one Apple Silicon Ultra computer with 512 GB of unified memory; the other listed quantizations require distributed inference.
Hugging Face offers remote deployment through Inference Endpoints and serverless inference through Inference Providers. A ready-to-deploy Inference Endpoints configuration runs FP8 weights on eight NVIDIA H200 GPUs, with support for up to 131,000 tokens of context and 16 simultaneous requests. Its API accepts images and supports tool calls, structured outputs and streaming.
Reasoning settings and fine-tuning
Reasoning effort can be set to low, medium or high, with high as the default. Reasoning cannot be disabled: setting it to none still uses high.
Fine-tuning with TRL is also supported from release. A Hugging Face example uses the FP8 variant on a node with eight B300 GPUs to train the model to reason in the language specified by a system prompt.