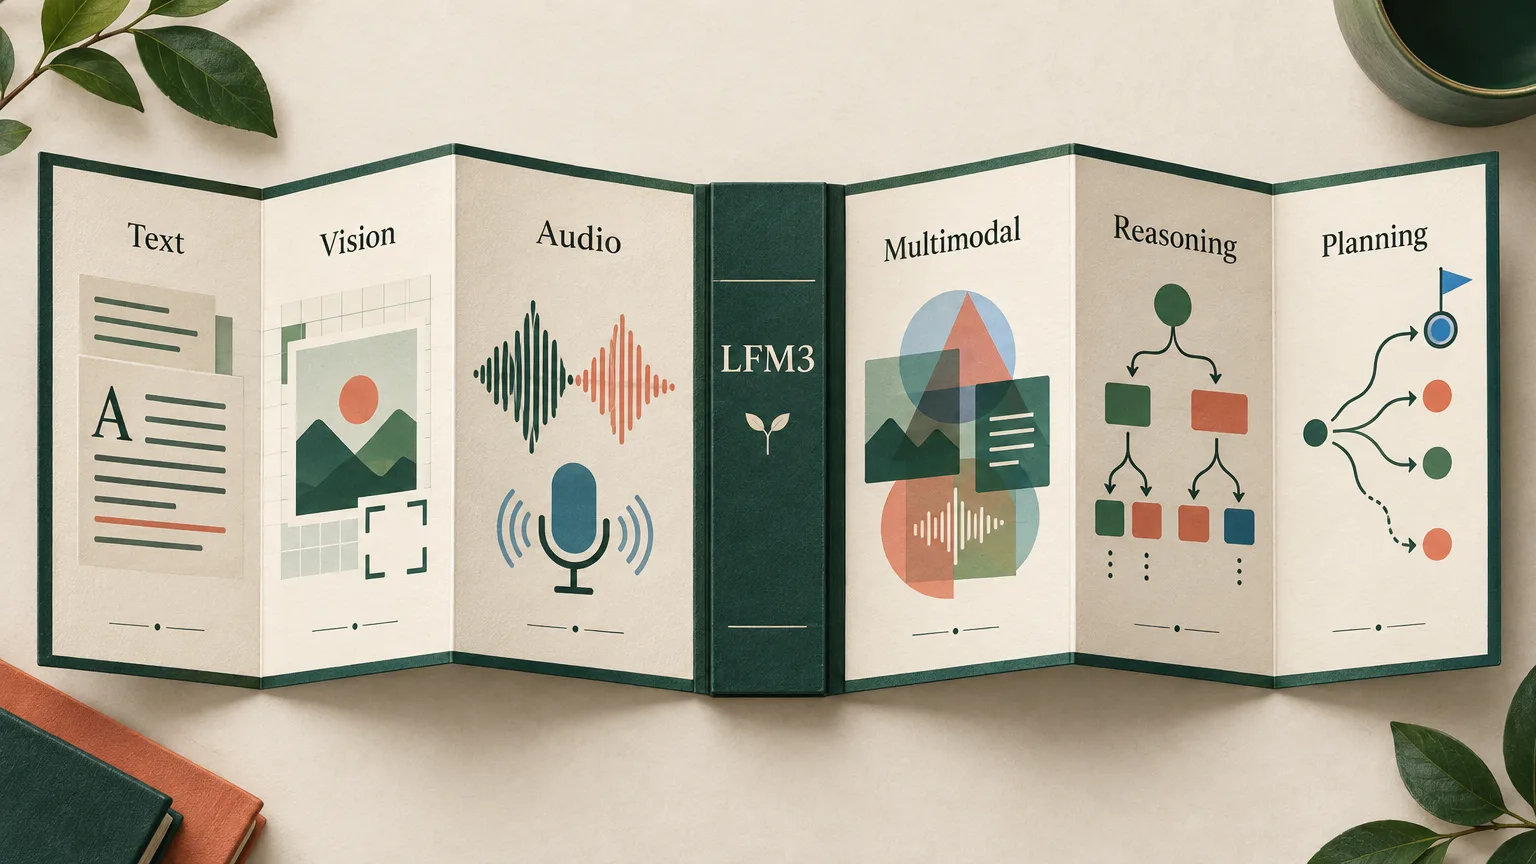
Liquid AI has released LFM3, a family of six small open-weight models for text, images, audio and structured decisions. The models are designed for fine-tuning on a single GPU and deployment on phones, laptops, edge systems and cloud hardware.
A shared base and a text model for agents
Each variant starts with LFM3-1.7B-Base and receives additional components and post-training for its intended task. The text model, LFM3-1.7B, supports tool use and agent workflows, with a context window of up to 256,000 tokens. Liquid AI says it outperforms the previous LFM2.5-2.6B despite having 35% fewer parameters.
The underlying architecture has 24 layers. Thirteen use short convolutions, five use sliding-window attention over the most recent 256 tokens, and six use global attention across the full available context.
Liquid AI’s agent tests put LFM3-1.7B at 45.6 for LiveClaw and 38.42 for WebArena-Verified. For Qwen3.5-9B, the respective results were 35.77 and 28.94. The company also recorded a score of 71.39 for the new model on BFCL V4, which evaluates function calling.
Memory and generation speed
Long contexts also require memory to retain attention state during generation. At a context length of 128,000 tokens, Liquid AI measured 1.6 GB of cache use for LFM3-1.7B. In the same comparison, Qwen3.5-4B used 4.3 GB and MiniCPM5-2B used 5.6 GB.
Using llama.cpp and Q4_0 four-bit quantization, the text model generated output 1.8 to 2.8 times faster than the next-fastest tested model across three target devices, according to Liquid AI.
The vision model also processes video
LFM3-VL-2B accepts images and video. Its new vision encoder has 164 million parameters and, according to Liquid AI, needs about one-third of the compute required by the SigLIP2 encoder used in the company’s earlier models. For video, it combines pairs of sampled frames into a single temporal slice, halving the resulting token sequence.
In Liquid AI’s aggregate comparison across 62 vision benchmarks, the model matched Gemma 4 12B and surpassed Gemini 3.5 Flash Lite. Vision tasks for agents were a weaker area: the model averaged 42.5 and trailed the most advanced systems substantially.
The company also demonstrated how the model could be specialized for wind-turbine inspection. After several hours of fine-tuning on one Nvidia A100 using approximately 3,000 public images, defect-classification accuracy rose from below 10% to 67% in its demonstration.
Liquid AI also tested the model for generating robotic control actions. It reported an average success rate of 96.2% across four LIBERO suites and 45.7% on RoboCasa-GR1 tabletop tasks.
Speech and multimodal input
LFM3-Audio-2B accepts and generates speech in 18 languages and supports tool calling. It can process incoming audio while someone is still speaking. Liquid AI measured time to first token as low as 50 milliseconds; total application latency also depends on end-of-speech detection, networking, tool execution and audio playback.
In Liquid AI’s internal tool-calling test, the audio model scored 58.5, compared with 44.3 for Qwen2.5-Omni-3B. On MMAR, a general audio-understanding test, Liquid AI reported a score of 50.6 for its model and 62.3 for MiMo-Audio-7B. Another variant, LFM3-Omni-2B, combines vision, audio and language in one model.
d1 models return structured answers
The two decision models accept an input and a list of questions, which they answer together in one pass. Their outputs can include boxes marking objects in images, excerpts from source text, numerical ranges or selections with calibrated probabilities. Alongside text and images, d1-Omni-2B also accepts audio.
Liquid AI says d1-2B has one-third fewer parameters than the previous d1-3B. In the company’s aggregate index of 117 benchmarks, it scored 63.2, compared with 58.8 for the older version.
Where the models are available
The model weights are available to download from Hugging Face. Hosted access is available through Liquid AI’s API and Playground, as well as Qualcomm AI Hub and Vercel.
Supported tools for running the models include llama.cpp, MLX, vLLM, Ollama, LM Studio, Unsloth and SGLang. The entire family is designed for fine-tuning on a single GPU.