

ElevenLabs Eleven v3 is the latest and most advanced text-to-speech model officially released by ElevenLabs for all users. Previously available only in alpha, the model now delivers significantly improved stability and accuracy when processing text.
Advanced Eleven v3 Voice Model
Eleven v3 is ElevenLabs’ most responsive AI voice model, offering exceptional emotional depth and rich delivery. Unlike previous models, it offers a wide dynamic range that can be controlled using inline audio tags directly in the text. The model supports more than 70 languages, including Czech, and enables the creation of natural conversations between multiple speakers.
A key new feature is Dialogue Mode, which connects multiple voices into a seamless conversation. Speakers share context and emotions, creating natural-sounding dialogue that resembles real human communication.
Dramatic Improvement in Accuracy
Since the alpha version, Eleven v3 has undergone significant improvements. In testing, users preferred the new version in 72% of cases over the previous alpha release. The greatest progress was made in accurately processing numbers, symbols, and specialized notation across languages.
The overall error rate decreased by 68% – from the original 15.3% to just 4.9%. The model can now correctly interpret context and decide how to pronounce the text. For example, it previously read the phone number "+49 170 9876543" as "plus forty-nine, one hundred seventy, nine million..." instead of correctly reading the individual digits.
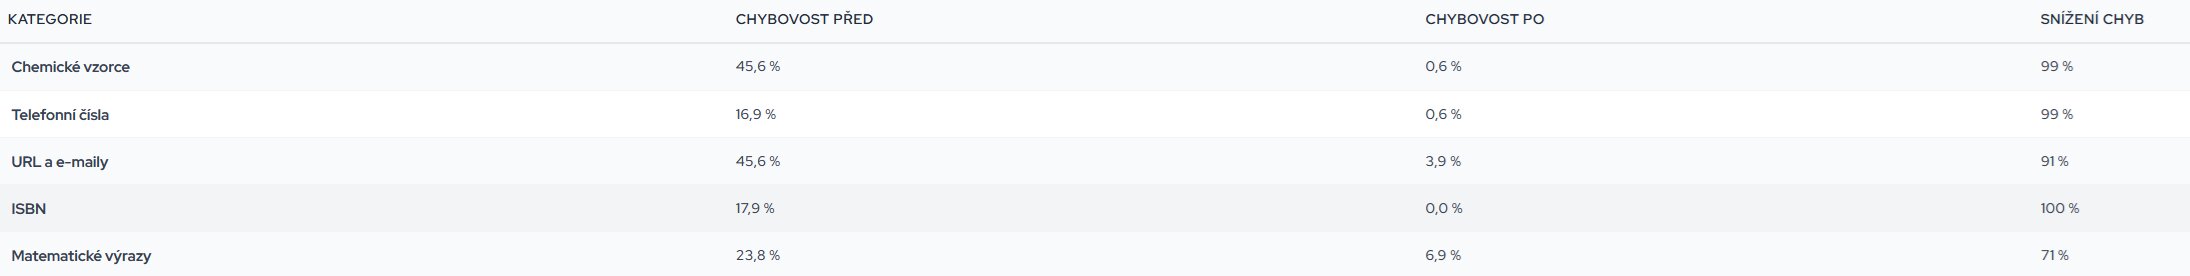
Examples of specific corrections include correctly reading currencies (¥250,000 now as "250,000 yen" instead of "25,000 yen"), chemical formulas (SO₂ as "S O two" instead of the garbled "sulfur double"), and sports scores (102-98 as "one hundred two to ninety-eight" instead of "one hundred two minus ninety-eight").
Control Over Emotions and Sound Effects
Eleven v3 enables full control over emotions, direction, and sound effects using audio tags. Users can insert tags such as [slowly] (slowly), [whispers] (whispers), [chuckles] (chuckles), [sad] (sadly), or [excited] (excitedly) into the text, which the model interprets and applies to the resulting voice.
The model supports a wide range of audio tags that are partially dependent on the voice and context. This feature creates controllable, expressive speech with layers of emotion, audio events, and immersive soundscapes.
Availability
Eleven v3 is now generally available on all platforms, including mobile devices. Developers can use the model through the public API, which supports both standard text-to-speech conversion and the exclusive multi-speaker dialogue feature. The model represents a significant advancement over the previous Eleven v2, which supported only 29 languages and basic tags such as pauses. Eleven v3 offers a full range of emotions, direction, and sound effects along with support for multiple speakers in Dialogue Mode.


