Alibaba launched the Qwen3-VL model in September and has now published a detailed technical report on this open multimodal model. The system excels at tasks involving solving mathematical problems based on images and can explore hours of video. It processes enormous amounts of data, such as a two-hour video or hundreds of pages of documents, within a context window of 256,000 tokens.
In "needle in a haystack" tests, the largest model, with 235 billion parameters, achieved 100% accuracy when searching for individual frames in thirty-minute videos. Even in two-hour videos containing roughly one million tokens, accuracy remained at 99.5%. The test works by randomly inserting an important, meaningful frame into a long video, which the system must then find and examine.
Benchmark results
In published comparisons, Qwen3-VL-235B-A22B often outperforms models such as Gemini 2.5 Pro, OpenAI GPT-5, and Claude Opus 4.1, even when competitors use advanced reasoning features or high thinking budgets. It excels at visual mathematics tasks: in the MathVista test, it achieved 85.8%, exceeding GPT-5's 81.3%. In MathVision, it led with 74.6%, ahead of Gemini 2.5 Pro at 73.3% and GPT-5 at 65.8%.
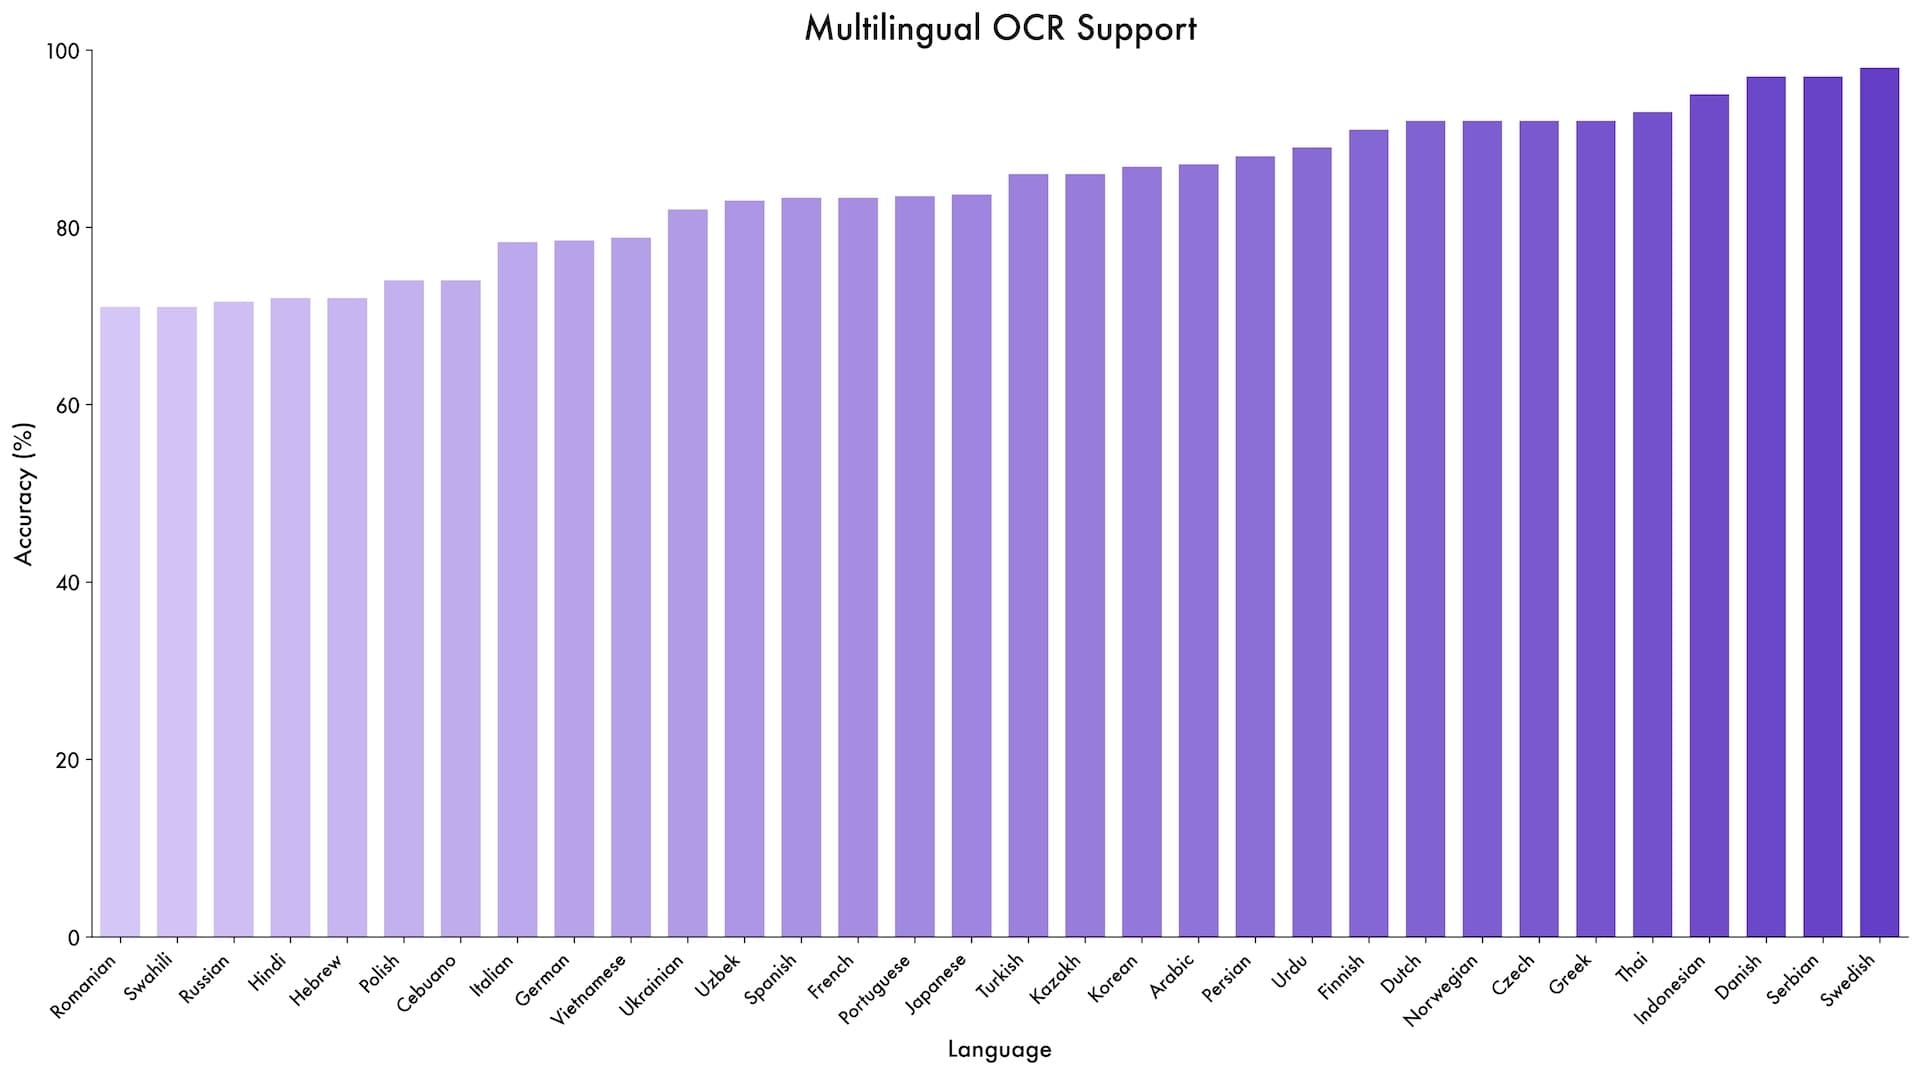
The model also performed well in specialized tests. It achieved 96.5% in DocVQA for document understanding and scored 875 points in OCRBench for text recognition. It supports 39 languages, nearly four times as many as the previous version. In optical character recognition (OCR), it achieved over 70% accuracy in 32 of those 39 languages.
Real-world capabilities
Alibaba claims that the system introduces innovations in graphical user interface (GUI) tasks. In ScreenSpot Pro, a test for navigating graphical interfaces, it achieved 61.8% accuracy. In AndroidWorld, where it must independently operate Android applications, Qwen3-VL-32B achieved 63.7%.
It can also process complex multi-page PDF documents. In MMLongBench-Doc for long-document analysis, it achieved 56.2%. In the CharXiv benchmark for scientific charts, it scored 90.5% on descriptive tasks and 66.2% on questions requiring complex reasoning.
However, it does not lead in every area. In the comprehensive MMMU-Pro test, it achieved 69.3%, below GPT-5's 78.4%. Competing models generally lead in video question answering. Qwen3-VL therefore appears to be a specialist in visual mathematics and documents, but it lags behind in general reasoning.
Technical improvements for better performance
The technical report describes three major architectural changes. The first is "interleaved MRoPE," which replaces the previous positioning method. Instead of grouping mathematical representations by dimension (temporal, horizontal, vertical), it now distributes them evenly across all available mathematical domains. This helps with long videos.
The second innovation is DeepStack technology, which gives the model access to intermediate outputs from the visual encoder, not just the final output. This provides the system with visual information at different levels of detail.
The third change is a text-based timestamp system that replaces the complex T-RoPE from Qwen2.5-VL. Instead of assigning a mathematical temporal position to each video frame, the system now inserts simple text markers such as "<3.8 seconds>" directly into the input. This simplifies the process and improves its understanding of temporal tasks in videos.
Training at enormous scale
Alibaba trained the model in four stages using up to 10,000 graphics processing units (GPUs). It first learned to connect images and text, then underwent full multimodal training on roughly one trillion tokens. Data sources included web scrapes, 3 million PDFs from Common Crawl, and more than 60 million tasks from STEM fields.
In later stages, the team gradually expanded the context window from 8,000 to 32,000 and finally to 262,000 tokens. The "Thinking" variants received specialized chain-of-thought training, enabling them to explicitly map out reasoning steps for better results on complex problems.
Openness and availability
All Qwen3-VL models released since September are available under the Apache 2.0 license with open weights on Hugging Face. The lineup includes dense variants ranging from 2 billion to 32 billion parameters, as well as mixture-of-experts models: 30B-A3B and the massive 235B-A22B.
Features such as extracting frames from long videos are not new—Google Gemini 1.5 Pro could already do this in early 2024—but Qwen3-VL offers comparable performance in an open package. The previous Qwen2.5-VL is widely used in research, so the new model will likely advance open development further.
Additional source: the-decoder.com