

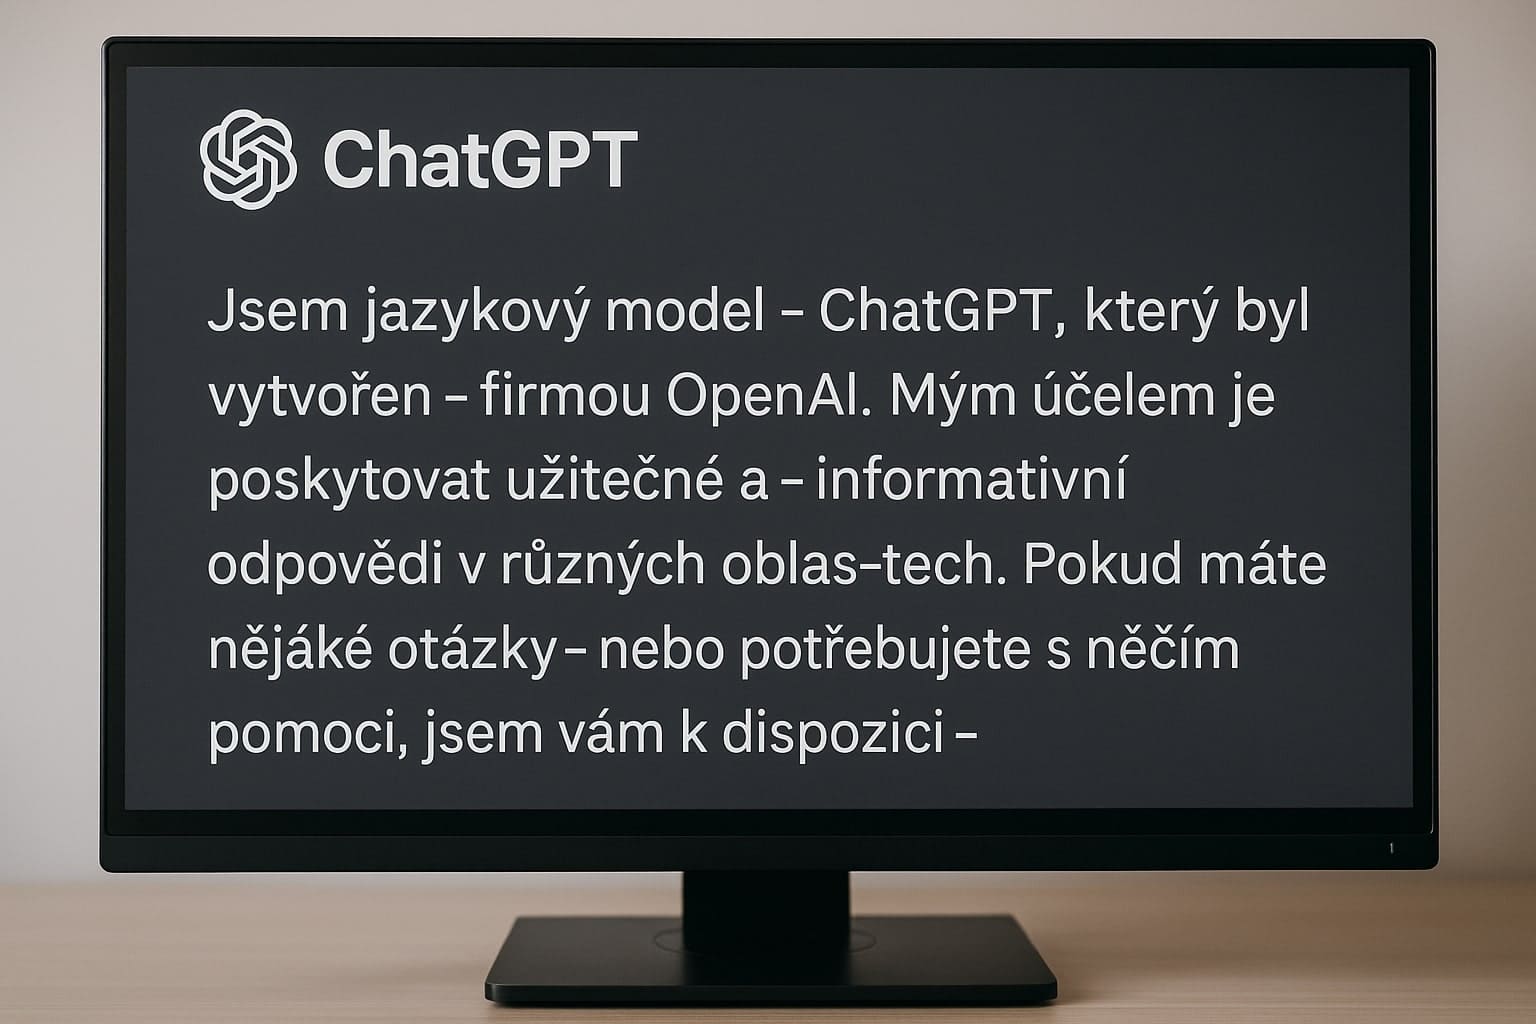
What is an em dash, and how does AI use it?
An em dash is used to separate ideas in a text—for example, to insert an explanation or create a pause. It appears occasionally in ordinary human writing, but texts produced by modern artificial intelligence models such as GPT-4o tend to contain many of them. Sean Goedecke noticed that a major change occurred between 2022 and 2024. The older GPT-3.5 model used em dashes similarly to people in contemporary texts, but the newer GPT-4o inserts them dramatically more often. This prompted him to investigate the reasons.
Goedecke compares data from different models and finds that this change is related to how these systems are trained. Artificial intelligence learns from enormous amounts of text used as training data. If this data changes, the AI’s writing style changes as well.
Main hypothesis: The digitization of old books
Sean Goedecke suggests that the key to this phenomenon lies in how training data is obtained for newer models. According to his analysis, OpenAI labs began using more digitized printed books between 2022 and 2024. These books often come from the 19th century, when the use of em dashes was at its peak. Specifically, he cites a study showing that the frequency of dashes reached its maximum in the 1860s.
Why old books in particular? Goedecke explains that older models such as GPT-3.5 were trained mainly on contemporary internet content, often from pirated sources. Newer models, however, need higher-quality data, so labs turn to publicly available digitized books from the past. These texts contain 30% more em dashes than modern writing. The result? AI learns this style and applies it in its outputs.
Goedecke notes that this change in data is not accidental. Labs are looking for ways to improve quality, and the digitization of older works provides them with rich material. Nevertheless, a paradox remains: even though AI uses so many em dashes, its overall writing style does not closely resemble that of the 19th century in other respects.
Alternative explanations considered by Goedecke
Goedecke does not stop at just one idea. He also mentions other possible reasons, but considers them less likely. For example, a process called RLHF (reinforcement learning from human feedback) might favor em dashes because they give text a conversational tone. People who evaluate AI outputs might prefer this kind of style.
Another idea involves platforms such as Medium, where double hyphens are automatically converted into em dashes. If the training data contained a large amount of content from Medium, this could influence the AI. Goedecke rejects this explanation as insufficient because it cannot account for the overall increase in usage.
Community reactions also appear in the comments on the article. One commenter claims that Medium’s behavior is behind it all, but Goedecke considers this explanation too narrow.
Why does the explanation remain speculative?
Sean Goedecke is candid and acknowledges that his conclusions are speculative. Without direct information about how OpenAI and other labs obtain their data, nothing can be confirmed with complete certainty. No single cause is universally accepted. Nevertheless, his main theory—that the digitization of older 19th-century books caused the increase in em dashes—appears to be the strongest.
This phenomenon also affects people: some authors now avoid em dashes so that their texts do not look AI-generated. Goedecke describes all of this in detail, but without unnecessary speculation beyond the available data.


