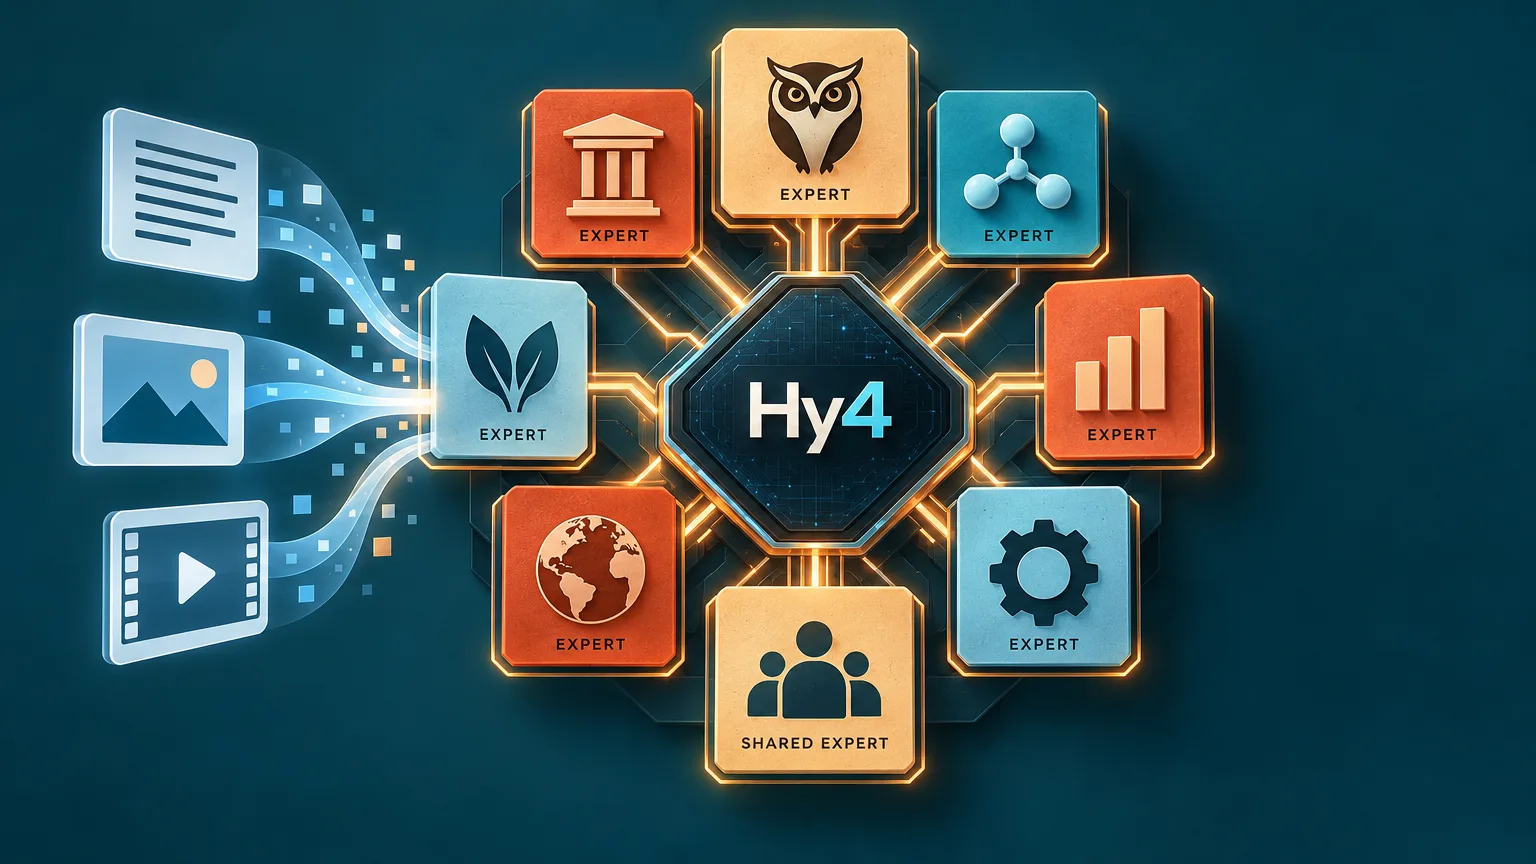
Tencent has released the weights for Hy4, a new model in its Hunyuan family. It accepts text, images and video and can process them together within a context window of up to 1,048,576 tokens. The model has 770 billion parameters in total and activates 49 billion for each token.
How Hy4 handles images and long context
A vision transformer with 1.23 billion parameters handles visual input. It converts images and video frames of varying resolutions into tokens that enter the same stack of layers as text.
For long contexts, Hy4 uses Gated DeepSeek Sparse Attention and IndexCache. An indexer selects the 2,048 positions it considers most relevant to each token, and the cache lets subsequent layers reuse that selection.
The model also includes DFly2, a decoder that proposes candidate tokens in advance. Its draft layers share the KV cache and selected positions with the corresponding Hy4 layers. Tencent says the decoder requires no additional KV-cache memory; actual speedups depend in part on how many proposed tokens are accepted and on support in the serving framework.
Comparisons with Hy3 and DeepSeek
In Tencent’s published comparison, Hy4 scored 57.2 on SimpleQA, a test of factual recall, while Hy3 preview scored 26.4. DeepSeek-V4-Pro-Base performed better on the MBPP-plus code-generation test, scoring 79.1 against Hy4’s 74.0.
In internal evaluations, Tencent reports that the hallucination rate fell from 15.76% for Hy4 preview to 5.45%. For a category the company defines internally as “speculative errors,” it reports a decline from 23.1% to 5.6%.
Tencent also says Hy4 trails closed models in research-level mathematics, long-horizon coding, model self-improvement and advanced visual question answering.
Finance, research and game development
Tencent also evaluated the model on 579 financial tasks with the participation of 213 finance professionals. The company says Hy4 received an average score of 3.04 and placed first among the open-weight models tested, ahead of DeepSeek-V4.1-Flash, Kimi K3.1 Pro and GLM-5.3.
Training with Tencent IEG developers focused on work involving Unreal Engine, Unity and Godot. Compared with the preview version, Tencent reports improvements of 19.1% on GameDev and 9.8% on GameLogic.
In TenureTrail, an internal benchmark comprising 123 research tasks across seven disciplines, Tencent says Hy4 ranked first among the open-weight models it tested.
Weights, memory and deployment
The language component uses a 78-layer mixture-of-experts architecture. Each mixture-of-experts layer has 256 routed experts and one shared expert; for each token, eight routed experts and the shared expert are activated.
The official repository offers weights in BF16 and FP8 formats. A community GGUF build is also available for quantized deployment and experimentation. The weights alone occupy roughly 1.54 TB in BF16 or 770 GB in FP8, before runtime overhead.
Tencent officially supports deployment through vLLM and SGLang and provides prebuilt Docker images. The company says the FP8 model can run across eight GPUs with tensor parallelism set to eight, provided they have sufficient aggregate memory, support FP8 and have the required sparse-attention kernels available.
The server offers an OpenAI-compatible API. The reasoning_effort parameter selects direct responses with “no_think” or extended reasoning with “high”. Native tool calls require the relevant hy_v4 parsers to be enabled.
Hy4 uses the custom Tencent Hy License rather than a standard OSI-approved license. Commercial deployment is subject to that license’s restrictions and obligations.