Arena has released a post-training method for text-to-image models that combines human-preference scoring with checks on specific prompt requirements. It applied the method to FLUX.2-dev and Ideogram 4. During training, the approach evaluates not just visual quality but also whether requested objects, their attributes and their relationships appear in the image.
Human preferences meet prompt-specific questions
According to Arena, its preference evaluator is a Bradley–Terry model trained on approximately five million human votes. Those votes came from pairwise comparisons of outputs from more than 100 models in Text-to-Image Arena. The evaluator estimates which of two images a person would prefer, converting that estimate into a score reflecting visual quality, composition and aesthetics.
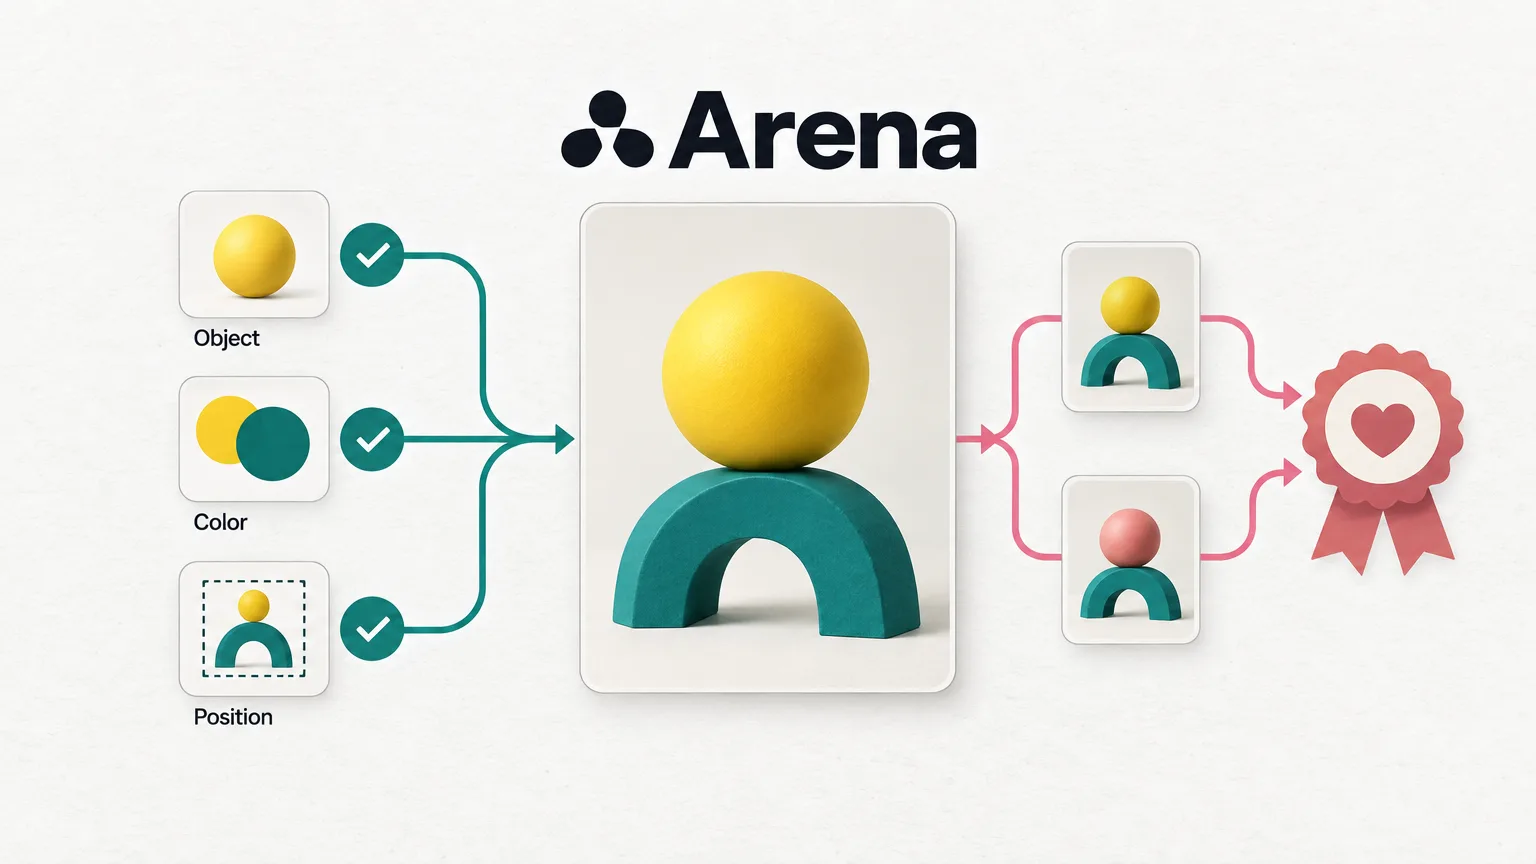
Arena also generates a separate prompt-faithfulness assessment for each training prompt. A language model first breaks the request into a tree of concrete yes-or-no questions. Some address objects and their attributes; others check spatial relationships or the requested style. A vision-language model then assesses the generated image, with the proportion of satisfied criteria determining the reward.
Arena says these individual assessments also help trace errors during training. The checklist identifies which requirement caused an image to lose reward—for example, a missing object, an incorrect attribute or a spatial relationship that was not preserved.
Stricter checks follow the prompt’s intent
Another part of Arena’s method checks for content that conflicts with the user’s intent. It targets unwanted objects, changes to the requested style and violations of negative instructions specifying what an image should not contain. Arena enables this check only for prompts requiring strict adherence, leaving more freedom for creative requests.
A detector limits rewards for known failures
A separate detector in Arena’s training method looks for known forms of reward hacking, including garbled text and an unwanted shift toward a photographic appearance. Rather than awarding additional positive points, it intervenes in the preference score of outputs it flags as problematic.
Arena caps the preference score of a flagged image at zero, preventing it from receiving positive preference credit for aesthetics or composition. Other samples retain their original scores.
The check covers only documented failure types. New ways of exploiting the reward require additional criteria or new detectors.
Model Soups merges variants into one model
Arena also describes training several variants with different reward configurations, all starting from the same base checkpoint. Using the Model Soups technique, it averages their parameter changes relative to that shared starting point, rather than running multiple models together during generation.
According to Arena, the shared starting checkpoint keeps the parameter changes aligned, producing a single merged model without additional inference-time ensemble costs. Arena also says the same method can work with open-source reward models such as Pickscore.
Results against the base model and on the live leaderboard
Arena used 10,000 real user prompts for training and reserved another 1,000 for evaluation. In its offline test, Gemini-3.5-Flash acted as the judge, comparing each post-trained output with an output from the frozen base model. It assessed each pair in both presentation orders to reduce position bias.
In this automated evaluation, Arena reports that the configuration with intent-gated constraints achieved a 64.2% win rate against the base model. After parameter merging, that rose to 66.0%, an increase of 1.8 percentage points. Gemini made the decisions in this test, rather than human voters.
On its live leaderboard, which uses human pairwise voting, Arena reports that post-trained FLUX.2-dev gained 69 Arena points. According to its results, post-trained Ideogram 4 reached 1,224 points and ranked above every publicly listed open-source model on that leaderboard as of September 4, 2026.
The reported results cover two base models. Live leaderboard scores can change as more human votes arrive and additional competing models enter the pool.