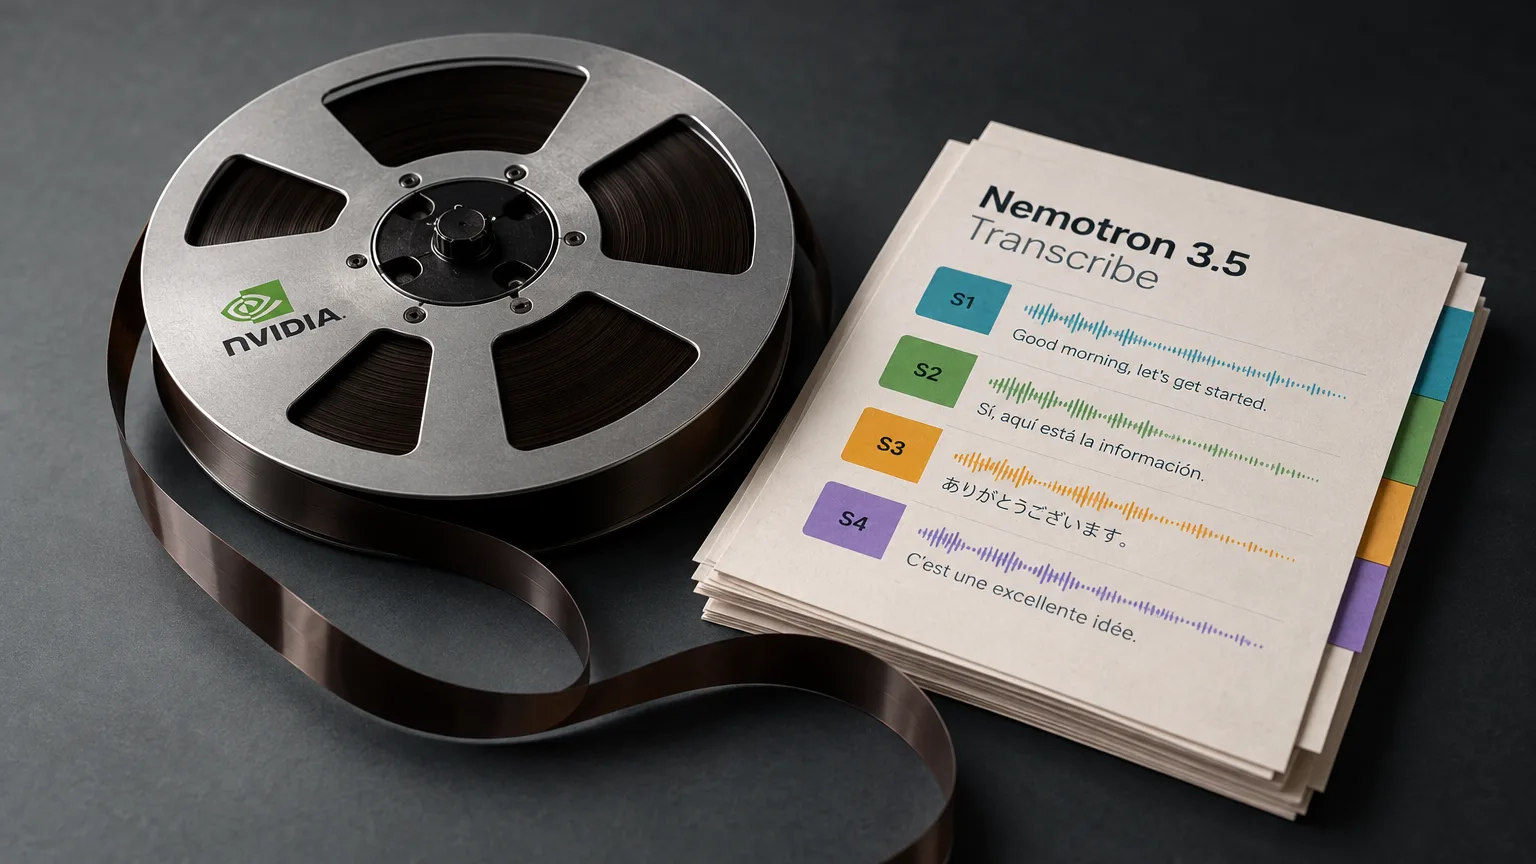
Nvidia released Nemotron 3.5 Transcribe on October 28, 2026, a free, open-weight model for transcribing audio in up to 40 languages. It also released the second version of Granary, its open-source speech dataset.
Translation and speaker identification
Nvidia says the model translates between English and 31 other languages in both directions. It can process recordings up to an hour long and distinguish up to eight speakers.
Transcribe works with recorded audio rather than live streams.
Tools for developers
The model and related tools are aimed at developers building apps for business meetings and medical transcription. Nvidia says developers can use the model alongside the updated Granary dataset and tools such as NeMo Speech to adapt apps to recognize specialized terminology in individual languages.
Single-chip operation and test results
The model has 30 billion parameters and, according to Nvidia, can run on a single chip. The company lists Jetson AGX Thor, DGX Spark and Blackwell data center chips among the supported options.
Nvidia also claims that the model outperforms rivals in benchmark tests, including Hugging Face's Open ASR Leaderboard.