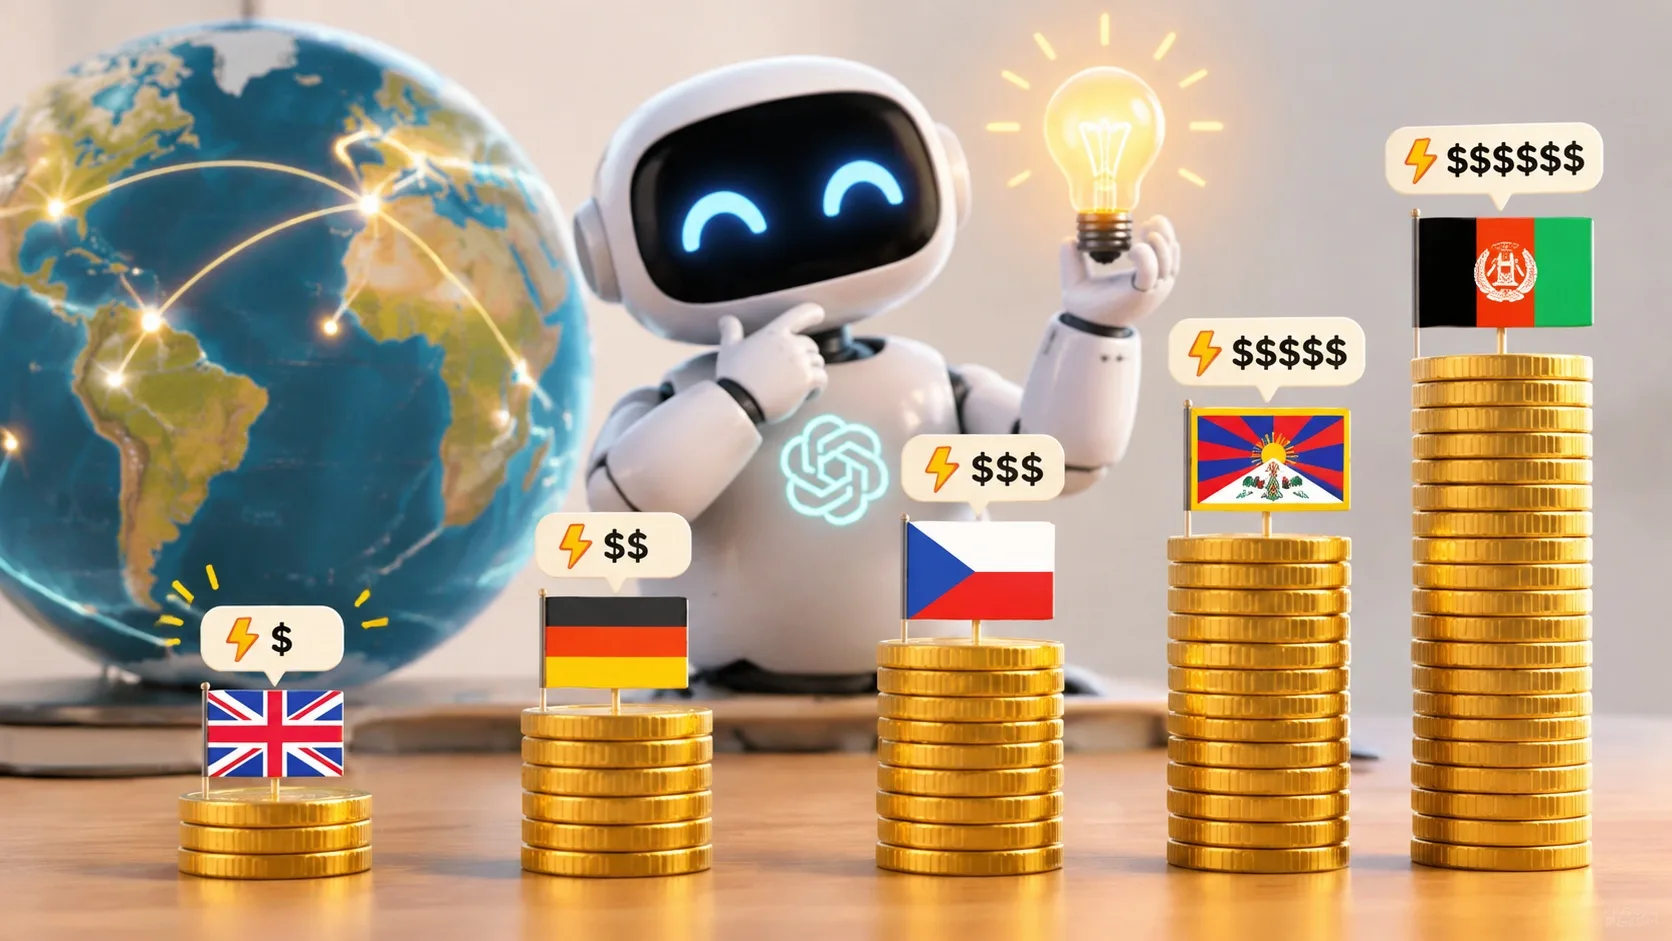
The same question, the same model, and the same computer. Yet energy consumption varies by as much as a factor of one hundred depending on the language in which the user asks. This is the conclusion reached by researchers from the University of Michigan, who, together with colleagues from Aberdeen and Cambridge, conducted the first thorough measurement of how much electricity language models consume when answering in 122 languages. The result is troubling: English is the least expensive, while languages such as Pashto or Tibetan require orders of magnitude more energy, even as the model provides significantly worse answers in them.
Why they undertook the measurements
Language models, or programs such as ChatGPT, are now used by people around the world in dozens of languages. When developers investigate how well a model handles different languages, they focus almost exclusively on the accuracy of its answers. Until now, few have paid much attention to how much energy the model consumes in the process.
Earlier studies had already shown that less widely spoken languages require more so-called tokens to express the same idea. A token is a small piece of text that the model works with, such as a whole word, a syllable, or even a single character. The more tokens the system processes, the more calculations it must perform. Until now, however, no one had measured actual consumption directly on the hardware. The authors therefore wanted to determine whether the language of a query consistently affects the energy required to answer it, and by how much. If it does, there is a risk that companies operating artificial intelligence systems will begin to sideline less widely spoken languages for purely economic reasons.
The researchers used the Belebele reading comprehension test, which contains the same texts and questions translated into 122 languages. In each language, they submitted 900 questions to the Qwen3 model with eight billion parameters and precisely measured the graphics card's energy consumption. All languages were tested under exactly the same conditions. As a control, they then repeated the measurements with additional models from Google and Meta, on two types of graphics cards, with varying numbers of queries processed simultaneously, and across three different tasks, ranging from reading comprehension and mathematical word problems to ordinary chat.
English for a penny, Pashto for a crown
The differences surprised even the authors themselves. One answer in English consumed an average of roughly 20 joules. A joule is the basic unit of energy, and for perspective, it is enough to know that one thousand joules make up a kilojoule. The same answer in Pashto, spoken mainly in Afghanistan and Pakistan, required roughly 3,500 joules. For the complete set of 900 questions, English consumed just under 18 kilojoules, while Pashto used more than 3,100 kilojoules, a 179-fold difference.
Pashto was closely followed by Tibetan, Shan from Myanmar, and Tigrinya, spoken in Eritrea and Ethiopia. However, the problem does not affect only less widely spoken languages. Hindi requires roughly eight times as much energy and Bengali about fifteen times as much as the same query in English, even though each is spoken by hundreds of millions of people. The researchers calculated that approximately 5.2 billion people must expend more than twice as much energy on text in their native language as English speakers. Most Western European languages required no more than twice as much energy as English.
Czech performed relatively well. The model consumed roughly four times as much energy in Czech as in English and answered 89 percent of the questions correctly. German performed slightly better, consuming roughly twice as much energy as English and achieving an accuracy rate of 92 percent. English had an accuracy rate of nearly 95 percent.
The measurements revealed another troubling fact. The model also performs worst in the languages that require the most energy. In Tibetan, Pashto, Tigrinya, Shan, and Amharic, it answered no more than 43 percent of the questions correctly, and in Shan, the figure was just under 11 percent. Speakers of these languages therefore pay twice over, because the answer is more expensive and often incorrect.
Where the energy is lost
According to the authors, the difference has two causes that amplify each other. The first is the number of tokens. A model trained primarily on English texts can break English words down efficiently, so one word often corresponds to one token. But in writing systems such as Tibetan, Ethiopic, or Burmese, a word is broken down into many tiny pieces. In Tibetan, there was an average of less than one letter per token, compared with almost five in English. For the four most energy-intensive languages, the model generated twenty to twenty-five times as many tokens as in English.
The second cause is the energy consumed per token, which varied by as much as a factor of eight between languages. Long responses take up more of the graphics card's memory. The server is then unable to process as many queries at once, the card's computing power remains underutilized, and each token becomes more expensive.
The researchers also examined what the model was actually writing in the problematic languages. In Tigrinya, it repeated the same sentence forty-five times in a row, as if it were stuck in a loop. In Latvian, it answered correctly but verbosely, generating more than three times as many tokens as in English. In Khmer, it switched to English and responded in a completely different language from the one in which the question had been asked.
The exceptions show that the complexity of the writing system is not the only factor. Simplified Chinese uses characters entirely different from the Latin alphabet, yet its energy consumption was the same as English because the model had seen an enormous amount of Chinese text during training. Egyptian Arabic performed similarly. Although it is among the less well-represented languages, it shares a script with Modern Standard Arabic, which the model knows well, and therefore ranked among the five least energy-intensive languages.
The gap did not disappear with larger models either. With the 14-billion-parameter Qwen3, the ratio between the least and most energy-intensive languages actually increased to a factor of twelve. English or Chinese was always the least energy-intensive, Tibetan or Shan the most, and the two groups of languages never overlapped. The results were the same on both graphics cards and across all three tasks.
What the researchers propose
The researchers want energy consumption to become a standard part of model evaluation, just like answer accuracy. In their view, developers should state how much energy each model consumes in individual languages. According to the authors, a model that answers 95 percent of questions correctly in English for a few pennies but only 22 percent in Tibetan at many times the cost is effectively two entirely different products for two groups of people.
They also propose practical solutions. The system could identify the language of a query and adjust the maximum response length accordingly to prevent the model from getting stuck in a loop. Queries in less widely spoken languages could be routed to smaller models specialized in those languages. Another option would be to translate the question into English, have the model answer it, and translate the result back. According to earlier research, this can also improve accuracy for less widely spoken languages. However, the authors warn that for texts full of cultural references, idioms, or local customs, the translation may sound fluent while still missing the meaning.
The authors recognize that their findings may also have a downside. Companies could use them as an excuse to restrict less widely spoken languages or remove them from their services altogether. But according to the researchers, remaining silent about the problem would be worse, because this would happen quietly and without oversight. Ultimately, everyone pays the bill for electricity, water, and emissions, while speakers of neglected languages receive the worst services.
The study also has its limitations. The tests were conducted on only two types of Nvidia graphics cards, and the researchers did not have access to commercial models such as GPT, Gemini, or Claude, which handle a large share of the world's multilingual queries. The questions were machine-translated rather than written by native speakers. Real-world user queries tend to be more chaotic, so the authors consider the measured differences to be a lower bound for what is actually happening.
Source: aclanthology.org