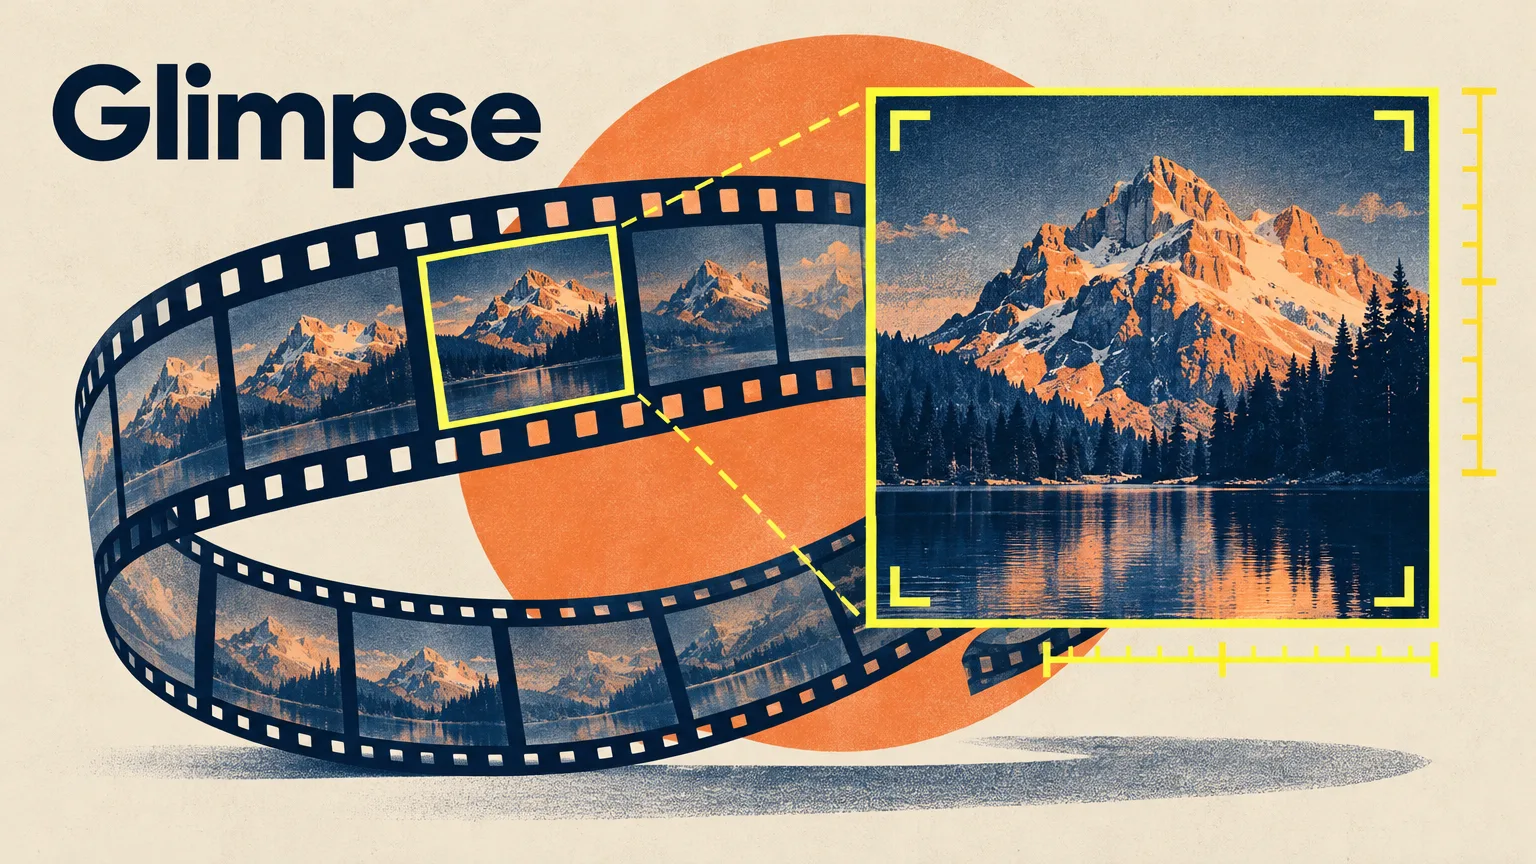
Startup Elorian released Glimpse, its first AI model focused on visual reasoning, on October 16, 2026. Available as a research preview, it works with images and video by returning to the original input during reasoning to examine particular details more closely.
Image crops, video frames and measurement through code
A mechanism Elorian calls visual scratch space gives the model several ways to revisit visual material while reasoning. Glimpse can crop a particular region of an image or select individual video frames. It can also execute code to measure and compare the content it sees.
Cropping and zooming during reasoning are not themselves new: OpenAI added that capability to its o-series models in 2025. Elorian says it built the entire Glimpse model around this approach.
Elorian reports an edge over GPT-6 Astra on two tasks
In Elorian’s evaluations, Glimpse outperforms GPT-6 Astra on reasoning about scientific charts and generating captions for short videos. The company describes its results on other visual reasoning tasks as competitive.
Elorian also says a small team trained Glimpse using a few hundred GPUs. According to the company, the model is substantially smaller than the frontier systems used in its comparisons.
API access is available; chat has a waitlist
The Glimpse research preview is accessible through an API, while users seeking the chat interface must join a waitlist. Input costs $0.60 per million tokens and output costs $3 per million tokens, placing it below Sonnet and Sol but above the lightweight Haiku and Luna models.
Elorian is initially targeting organizations that handle large amounts of video. Its intended customers include robotics companies and scientific laboratories, alongside media and creative businesses.
A longer-term plan to connect perception with action
Elorian’s longer-term goal is to connect scene modeling with decisions about which action to take. That ambition includes directly controlling robots.